AI Databases & Context Infrastructure
Databases and context systems for agent memory, knowledge retrieval, graph reasoning, hybrid search, and production AI data workflows.
8 tools, updated November 2026
Infino
Open-source retrieval over Parquet, combining keywords, vectors and SQL for AI applications.
Freemium
SuperLocalMemory
Keep project facts, decisions and rules available to your connected AI assistants.
Free

Crosswalk
Give your AI a private newsletter inbox, feeds and reusable notes.
Free
Context.dev
Scrape, search, crawl and monitor the web through one API for AI agents and RAG applications.
Freemium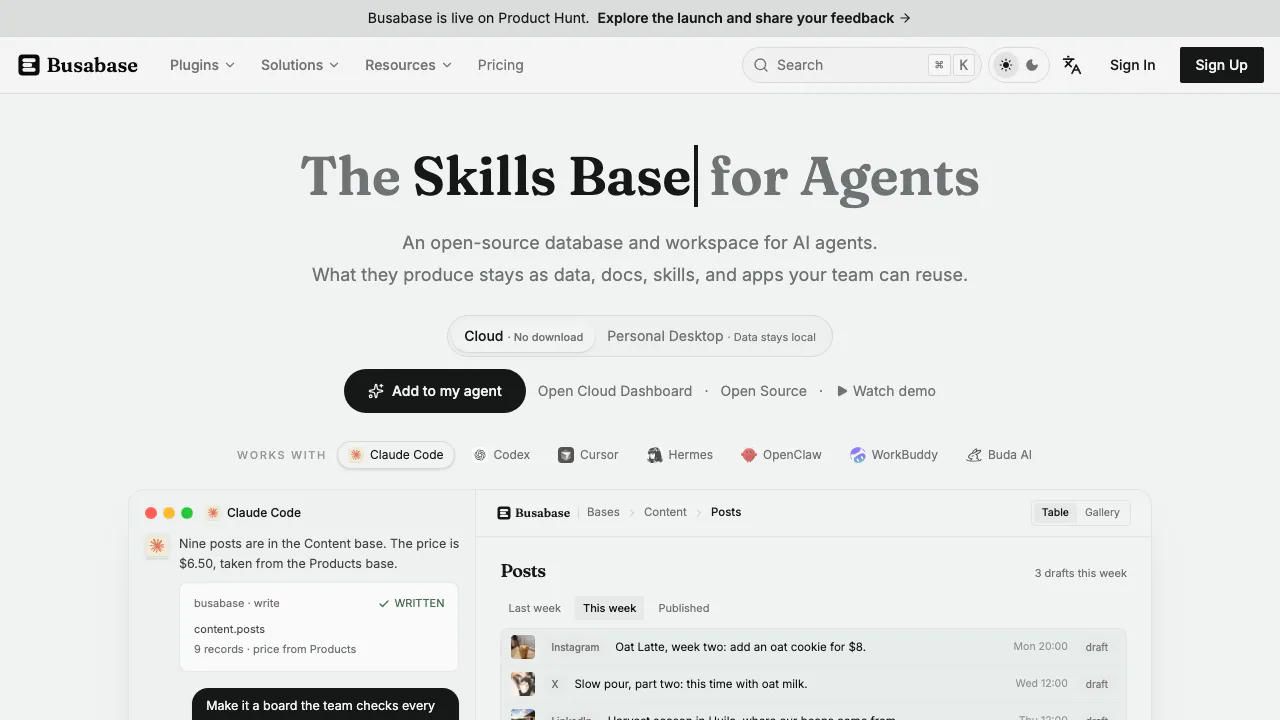
Busabase
Keep agent-written records, documents, skills and apps in a workspace your team can review and reuse.
Freemium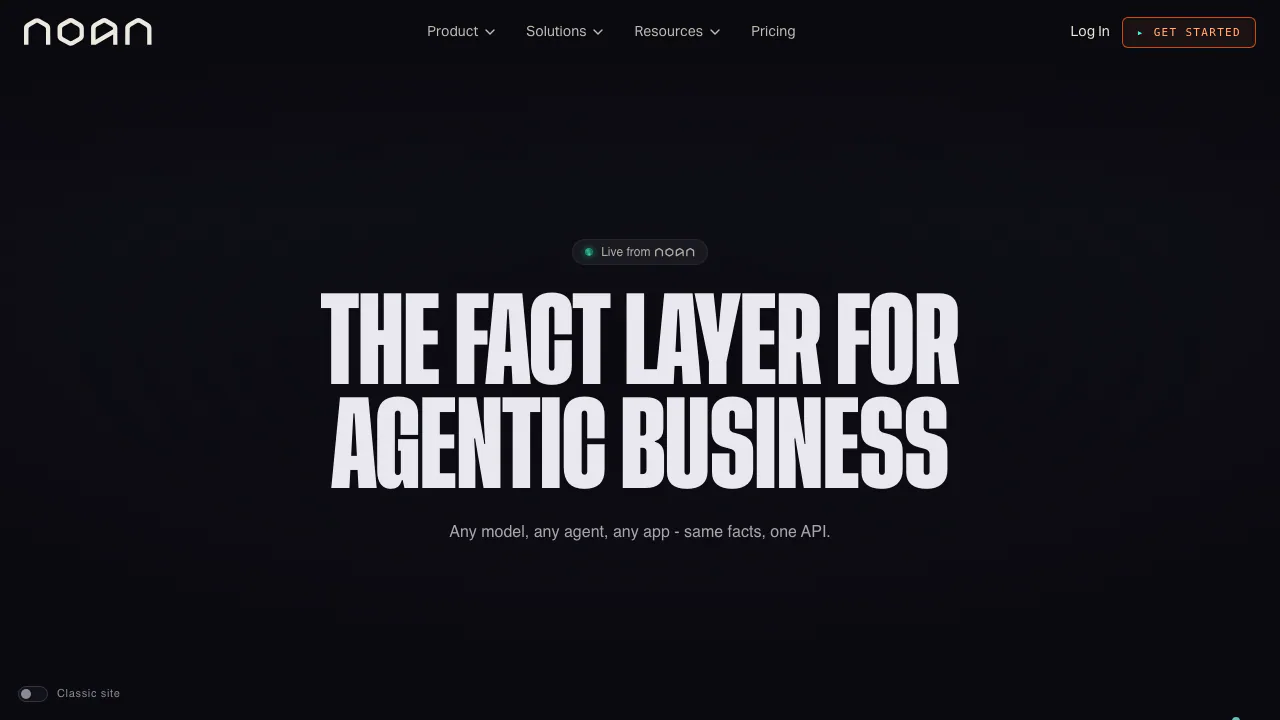

NOAN
Approved company facts for agents, apps and teams.
Freemium

Maximem Synap
Freemium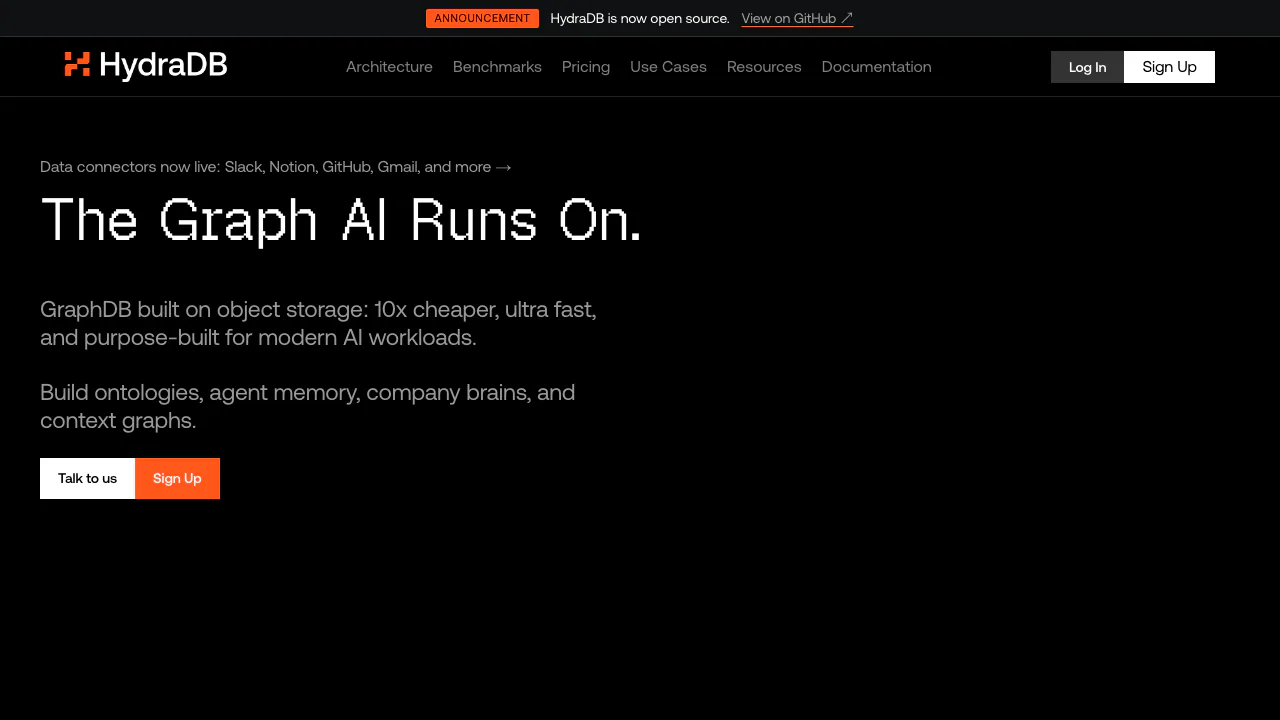
HydraDB
Open-source graph database and context layer for stateful AI agents
Freemium
AI databases and context infrastructure give AI applications a durable place to store, connect, and retrieve the information they need at run time. This category covers developer-facing systems for agent memory, knowledge bases, contextual retrieval, graph relationships, vector search, and the data layer behind retrieval-augmented generation.
What are AI databases and context infrastructure?
In plain language, these tools keep an AI application from starting every request with no memory. They can store documents, conversations, preferences, entities, events, and relationships, then return relevant context when an agent or model needs it. Some products are vector databases focused on similarity search; others combine graphs, metadata, keywords, temporal history, or relational queries to preserve more structure.
Common use cases
Teams use this infrastructure to build assistants that remember users across sessions, internal knowledge agents grounded in company material, support agents that retrieve customer history, and coding or research agents that work across large collections. Graph-oriented systems can be useful when the answer depends on relationships, ownership, chronology, or changing facts rather than simple semantic similarity.
How to compare the options
Start with the retrieval task. Check which inputs can be ingested, how indexing works, whether queries return citations or structured context, and how tenants or users are isolated. Review SDK and API support, metadata filters, graph or vector capabilities, latency claims, observability, and integration with your preferred model stack. If you need to migrate an existing application, look for compatible protocols, import paths, and clear limits.
Deployment, pricing, and data controls
Separate hosted-service terms from open-source software licenses. A public repository does not automatically make the managed cloud free, and self-hosting may involve different operational costs or commercial conditions. Compare storage and query billing, free allowances, overage rates, backup responsibilities, data residency, encryption, retention, and whether submitted data may be used to improve a service.
Choose by workflow, not by label
“AI database” can describe very different products, from a vector store to a full context platform. Shortlist tools by the job your application must complete, test them with representative queries and updates, and verify important security or pricing claims on the provider’s current documentation before production use.